Your first pipeline
The end-to-end path from a first source file to a scheduled data product. Work through the four stages in order — each one builds on what the previous one registered in the metadata.
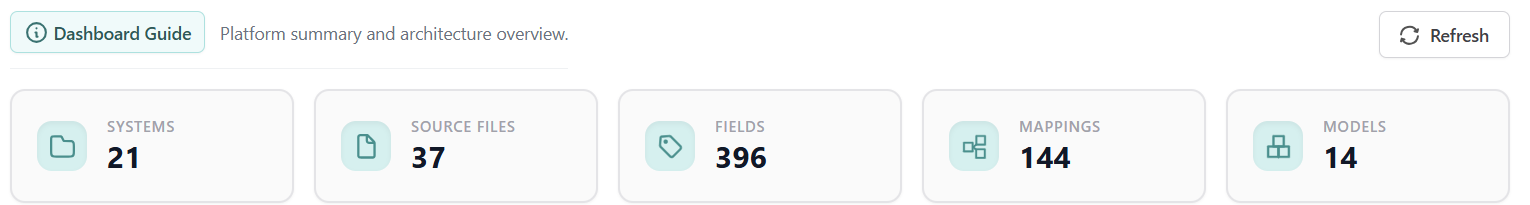
The dashboard is the quickest way to confirm that each step below has registered. The counters at the top track the systems, source files, fields, mappings and models that exist in your installation.
The platform has to be installed and reachable, and the installation-wide settings set. See Deploy, and read Fundamentals if you have not already.
The platform works by discovery: a deviation against the data contract is recorded, not blocked. Nothing is filtered out between the zones — see What the platform records, and what it stops.
A few configuration gaps produce no error at all, and leave data missing. Read Silent failure modes before you go looking for a bug.
Stage 1 — Start with DLS
Define what a delivery looks like before you automate producing one. If you have no source copy to work from, start at Stage 2 instead and come back here.
- Set up DLS. Create a system in the metadata, add a source file, and configure it. Set the correct file pattern and the preferred folder structure for the archive (raw) and Published Data (trusted). Upload some sample data to the Landing zone — as large as possible, since it will represent the data contract when you go live.
- Monitor the process. Wait for the process to finish. Go to DataOps and DLS Trace to follow it.
- Verify new fields. Go to DLS Discover New Fields. Check that the new fields and levels in the list are correct, then press Publish New Fields.
- Deploy the staging structure. Go to Documentation, select your system and source file, open the list of levels and fields, and press the SQL tab. Copy the SQL into your target database and deploy the staging structure.
Full field reference: Data Lake Service (DLS).
Stage 2 — Continue with INGEST
- Configure the source connection. In the Config UI, configure your source connection with all required credentials and parameters.
- Configure the data import. In the Config UI, configure a data import for each table or API endpoint.
- Monitor INGEST tasks. Go to DataOps and follow progress under INGEST Tasks.
INGEST tasks start by default directly after submission. If you expect a delivery today and see nothing, check the schedule before assuming a failure.
Full field reference: Ingest.
Stage 3 — Build an integrated data model
- Configure the business core concept model. In the Config UI, add columns, business keys and relationships to other model objects.
- Generate and deploy the model tables. Use the SQL Generator API or the CI/CD tool to generate all model target physical tables, and deploy them to your target database environment.
- Map the target model objects from your source data using the saved data contracts. The Config UI is the simplest route; the APIs give you extended functionality.
- Configure the loading schedule. In the DataOps UI, go to DWA Schedules and set your preferred schedule.
- Monitor DWA tasks in DataOps, under DWA Loading Tasks.
A mapping group must contain at least one key mapping and one attribute mapping, or nothing loads — See Data Warehouse Automation (DWA).
Stage 4 — Create and schedule data products
- Create the data product logic. Deploy it as a stored procedure in your target environment.
- Add dependencies for the new stored procedure using the API.
- Monitor additional tasks in the DataOps UI, under DWA Additional Tasks.
Next steps
- Daily operations — the routine that keeps the pipeline you just built healthy
- Platform guide — layer-by-layer detail on everything you configured above, across the INGEST, DLS and DWA pages
- FAQ and Known issues — when something does not behave as described
- Silent failure modes — when nothing reports a problem and the data is still missing
Interested in contributing? Please reach out to us and we will coordinate the next steps.